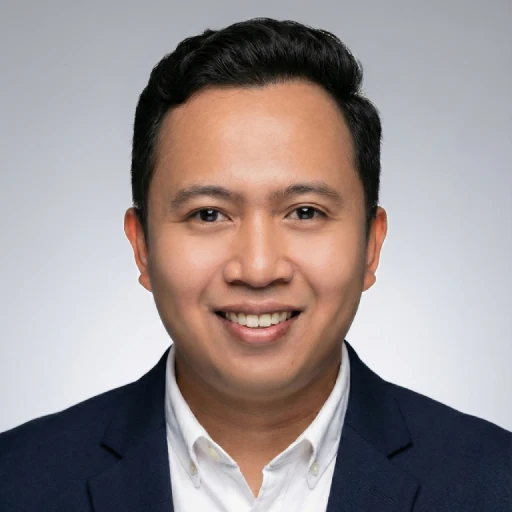
Habib Abdurrasyid
AI/ML Engineer
I'm Habib Abdurrasyid. rasyidev is the name I use online.
Building practical AI systems with machine learning, LLMs, and production engineering.
I work on applied machine learning, LLM applications, and RAG pipelines. I care about the part after the demo too: evaluation, APIs, data, and the work needed to keep a system useful.
My day job is Software Engineer, Data Platform at XLSmart. I build FastAPI services and Spark jobs, and work with PostgreSQL plus data tooling across AWS and Tencent Cloud. That work is not my headline, but it gives me a better feel for the systems underneath AI products.
Before that I taught AI/ML to more than a thousand students for about four years. It made me suspicious of explanations that sound good but fall apart under a beginner's question.
I write here about experiments, decisions, and the parts that cost me time. Some projects are still being figured out in public.
👋 Get to know me
Where I've worked and why I ended up caring this much about data plumbing.
🛠 Things I've built
Data pipelines, ML tools, and one dashboard that tracked buses live. The write-ups include what broke.
✍️ Notes from the work
Mostly the parts that cost me time: slow queries, wrong assumptions, and whatever finally worked.
💡 Today I learned
Short notes, one lesson at a time. The small things that unblocked real work.
🧰 What I use
The tools running in my real work: APIs, data, LLMs, and cloud. No shelfware.
🏆 Certifications
The exams I've sat and the training I've finished. Every one verifiable on Credly.
📄 Download my resume
Experience, skills, and projects in one PDF.
Latest Articles
My Pricing Machine Could Not Answer Questions, So I Built It a Brain
Print-Cost priced documents but went silent otherwise. The story of giving it a voice: an assistant that answers shop questions and never invents a price.
Building a Scalable ETL Pipeline with AWS Glue (CSV to Parquet + Partitioning)
A hands-on walkthrough of a serverless ETL pipeline with AWS Glue, PySpark and Athena: raw CSV into partitioned Parquet for fast queries at scale.
Creating Learner Progress Monitoring Using Python, Pandas and Streamlit
How I built an automated learner progress dashboard with Python, Pandas and Streamlit, tracking assessment scores and participation across Canvas LMS cohorts.
The Print Shop in My Head: Pricing Documents by Gut Feel
In college I ran a small print shop and priced every document by instinct. Years later I taught a machine to do it with K-Means and XGBoost.
Featured Projects
Dokuprint Agent
Agentic RAG assistant for a print shop (LangGraph, Qdrant, LangFuse): prices PDFs and answers questions. 94.7% hit@5, zero invented prices across 47 evals.
Print Cost
ML document pricing (K-Means + XGBoost, 99% F1): prices PDFs at 7 DPI in 5 ink bands. 109 pages/sec via FastAPI + Streamlit, live on Hugging Face.